
Abstract
We introduce Massively Multi-Task Model-Based Policy Optimization (M3PO), a scalable model-based reinforcement learning (MBRL) framework designed to address sample inefficiency in single-task settings and poor generalization in multi-task domains. Existing model-based approaches like DreamerV3 rely on pixel-level generative models that neglect control-centric representations, while model-free methods such as PPO suffer from high sample complexity and weak exploration. M3PO integrates an implicit world model, trained to predict task outcomes without observation reconstruction, with a hybrid exploration strategy that combines model-based planning and model-free uncertainty-driven bonuses. This eliminates the bias-variance trade-off in prior methods by using discrepancies between model-based and model-free value estimates to guide exploration, while maintaining stable policy updates through a trust-region optimizer. M3PO provides an efficient and robust alternative to existing model-based policy optimization approaches and achieves state-of-the-art performance across multiple benchmarks.
Video
M3PO Learns Diverse Tasks
We evaluate M3PO on 189 control tasks across multiple task domains: DMControl, Meta-World and DMLab.
1. Single Task Benchmarking
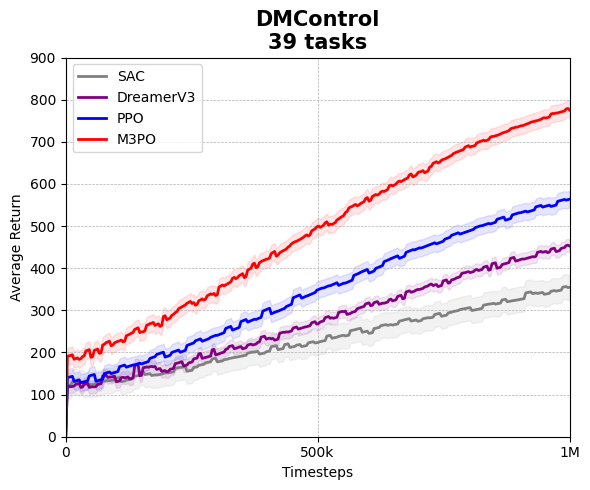
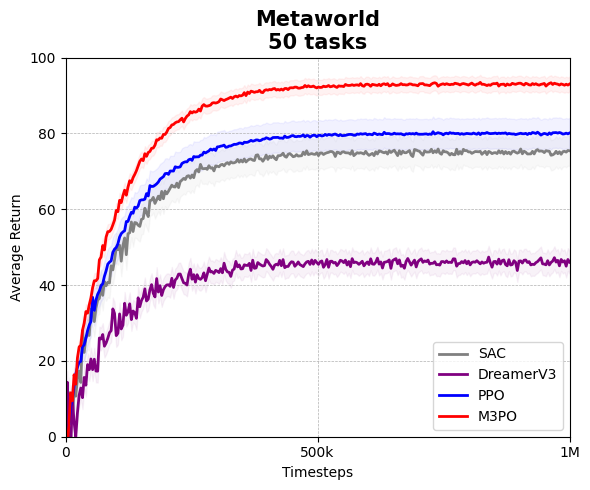
M3PO outperforms model-free methods (PPO, SAC) and DreamerV3 across 39 DMControl and 50 MetaWorld tasks, achieving higher returns and faster convergence.
2. Multi Task Benchmarking
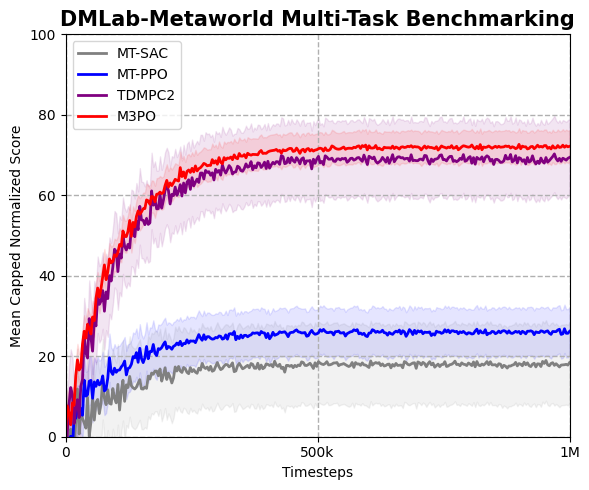
On 80 combined DMLab+MetaWorld tasks, M3PO and TD-MPC2 reach ~85–90% normalized score; M3PO shows notably tighter confidence bands for more stable learning.
3. Vectorized Benchmarking
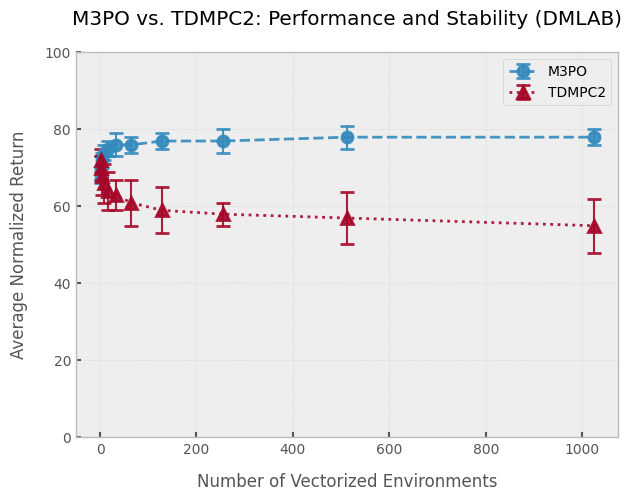
As environment vectorization increases, M3PO maintains high average returns, whereas TD-MPC2’s performance and stability degrade under heavy parallelism.
BibTeX
@misc{narendra2025m3pomassivelymultitaskmodelbased,
      title={M3PO: Massively Multi-Task Model-Based Policy Optimization},
      author={Aditya Narendra and Dmitry Makarov and Aleksandr Panov},
      year={2025},
      eprint={2506.21782},
      archivePrefix={arXiv},
      primaryClass={cs.LG},
      url={https://arxiv.org/abs/2506.21782},
}